How do scalar grounding losses shape RepTok decoding?
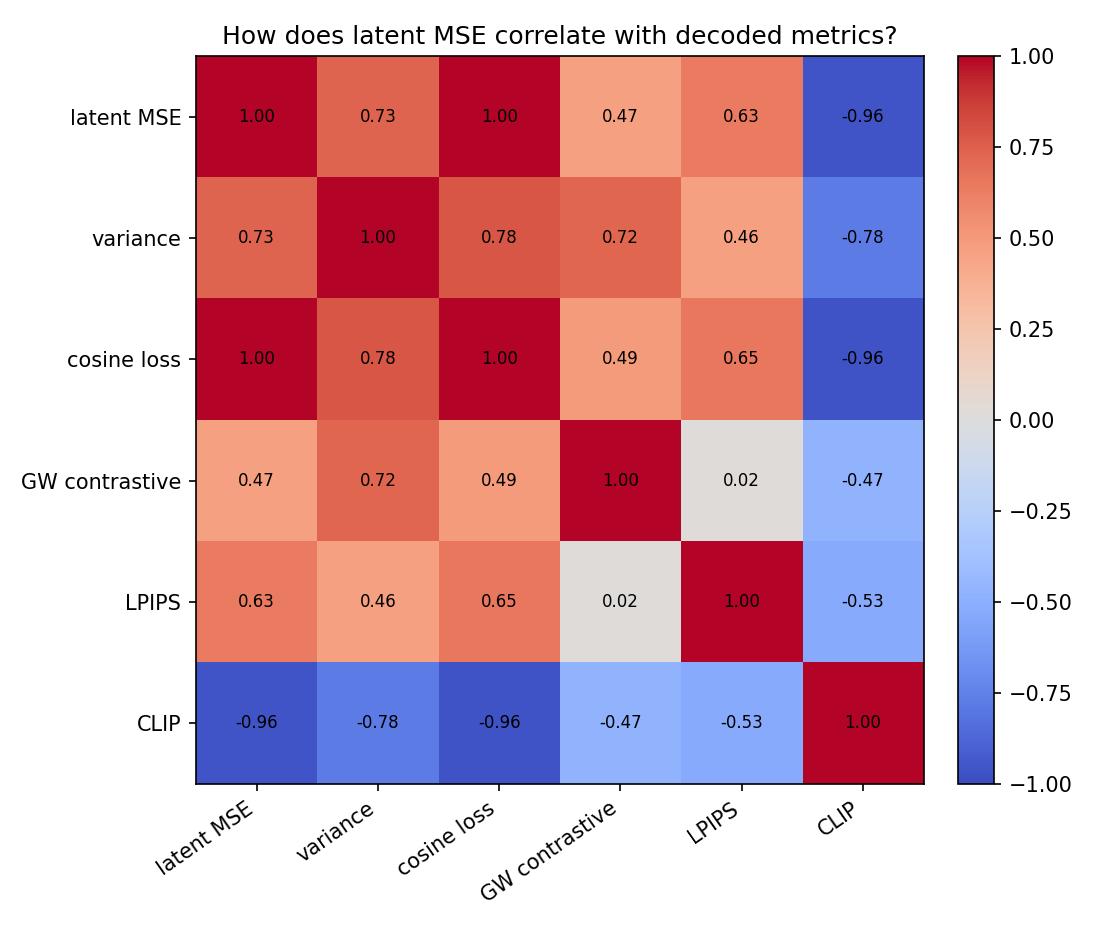
Question 1: how do the validation metrics agree with each other?
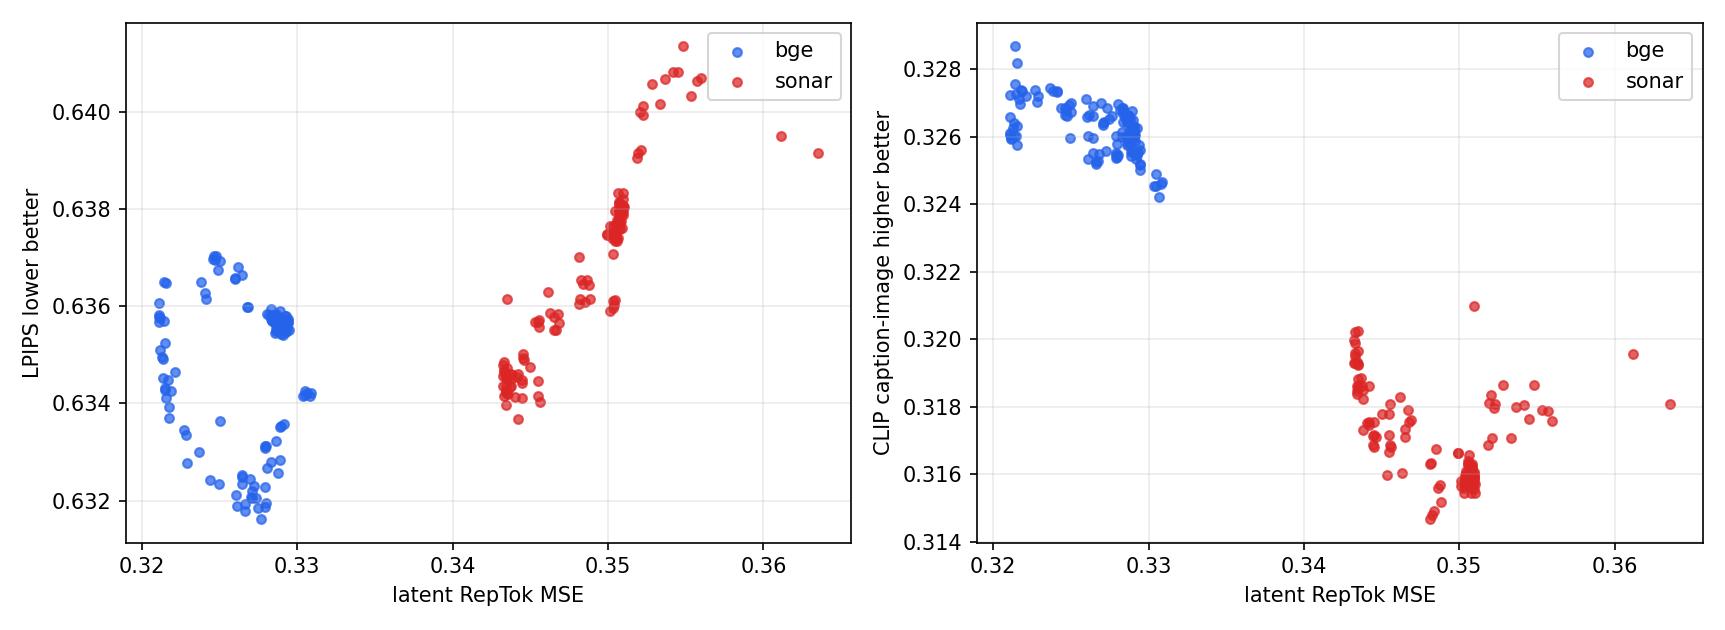
Question 2: how does each objective correlate to each metric?

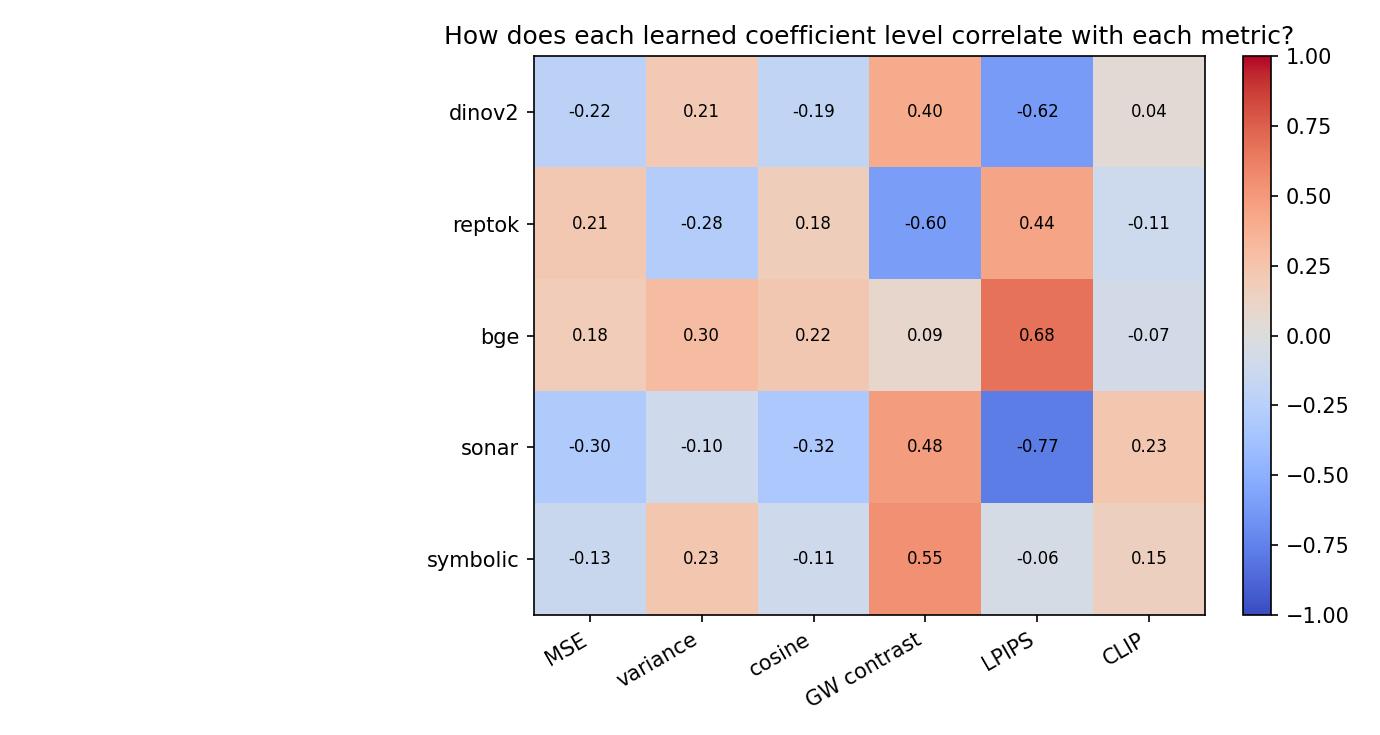
Question 3: how does each learned coefficient's level correlate to each metric?
Question 4: what do pure-objective coefficient runs learn?


Question 5: which loss recipes rank best by latent MSE?

Question 6: which loss recipes rank best by LPIPS?

Question 7: which loss recipes rank best by CLIP?

Question 8: how well does learned fusion actually work?

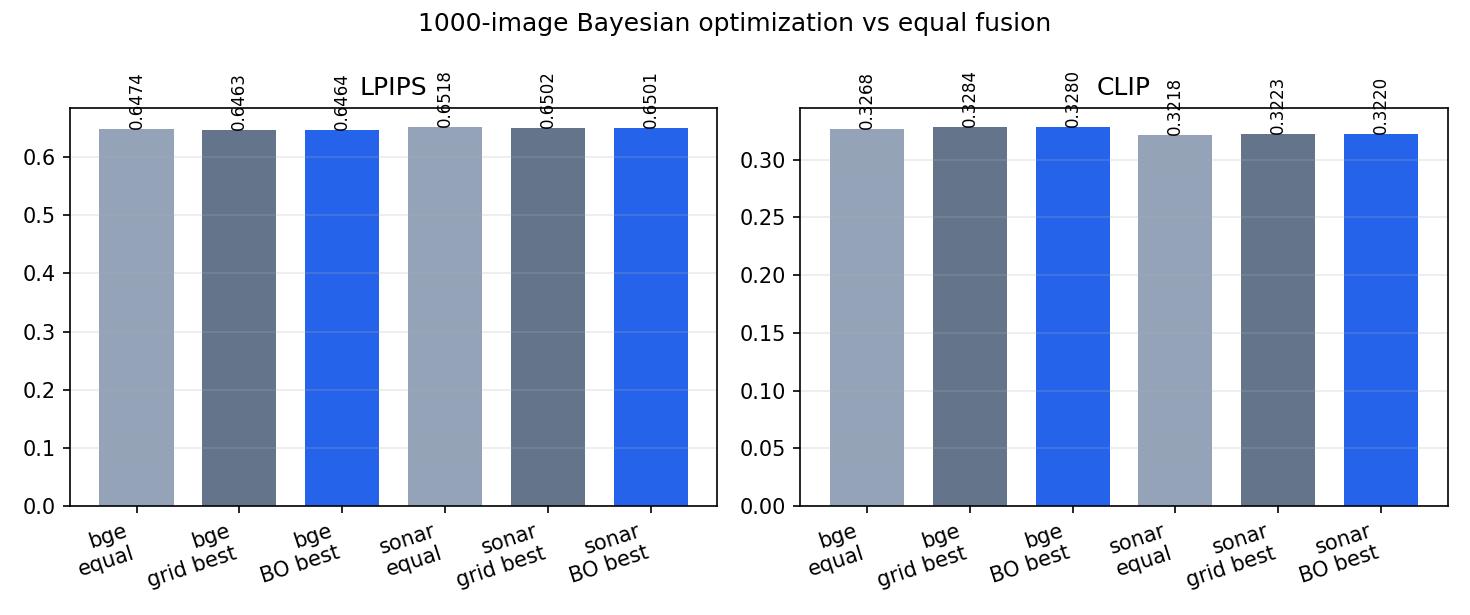
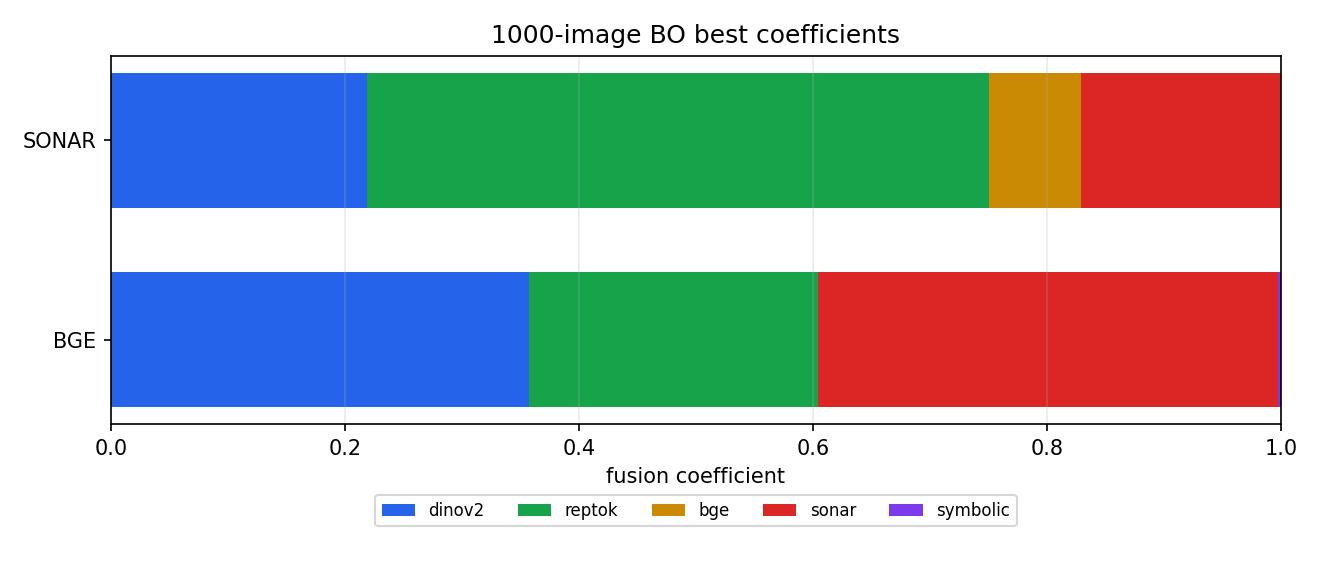
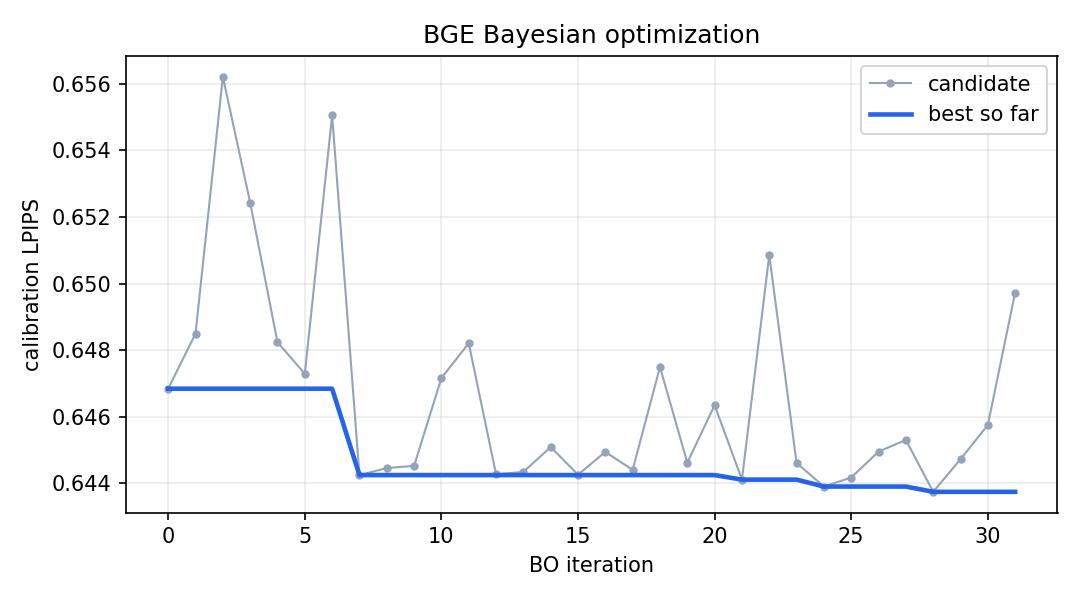
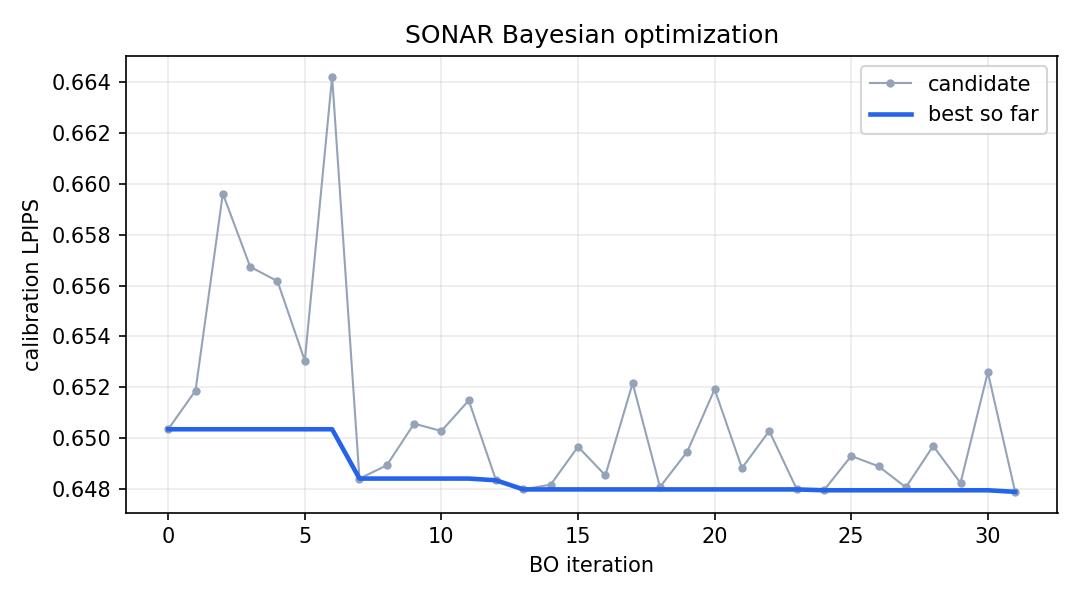
Question 9: does Bayesian optimization directly on LPIPS beat equal fusion?